About Me
I am a 3rd year Ph.D. student at UNC Chapel Hill (MURGe-Lab), advised by Prof. Mohit Bansal, and have interned at Adobe Research and Meta Superintelligence Labs, joining Google XR in Dec 2026.
Research Direction
- Video (Multimodal) Reasoning, Generation, and Understanding, with RL and post-training.
- Embodied AI with Diverse Sensor Modalities, including gaze, audio, 3D LiDAR, HD maps, and other multimodal signals.
AI that thinks and acts according to what it senses.
How can we expand what AI can sense, and how should its intelligence adapt to what it senses?
drag to rotate ↻
The physical world never reveals itself through one modality. Cameras see part of the kitchen; gaze shows where her attention is, audio hears the kettle, LiDAR maps 3D space.
Toggle the sensors to see what each one adds.
The agent fuses this evidence and adapts how it reasons to it, and also recognizes when perception is not enough: the medicine bottle is hidden.
So it acts to get the evidence it needs: it moves for a clearer view, confirms the bottle by touch, and proactively alerts her. Each action reshapes what it perceives next.
News
Publications
-
 preprint
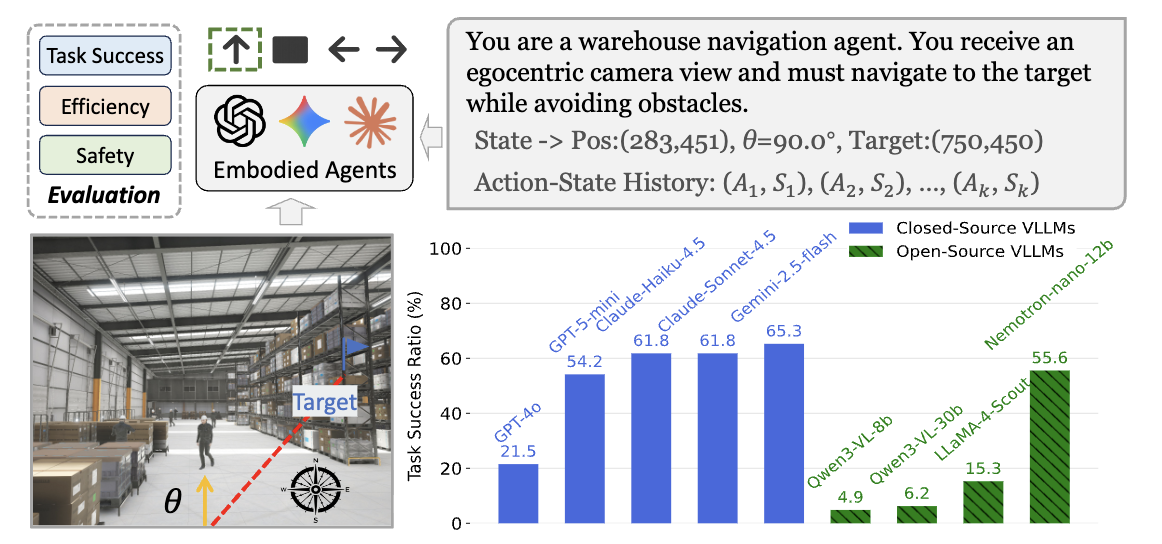
🔎 Can robots reason about space in dynamic industrial environments?preprint
-
 NeurIPS
🔎 How far current streaming video understanding to AR glasses?The 40th Neural Information Processing Systems, Evaluations and Datasets Track (NeurIPS), 2026.Also accepted to CVPR 2026 with strong scores (5/5/5) but desk-rejected after camera-ready because of coauthor's reviewing issue.
-
 ECCV
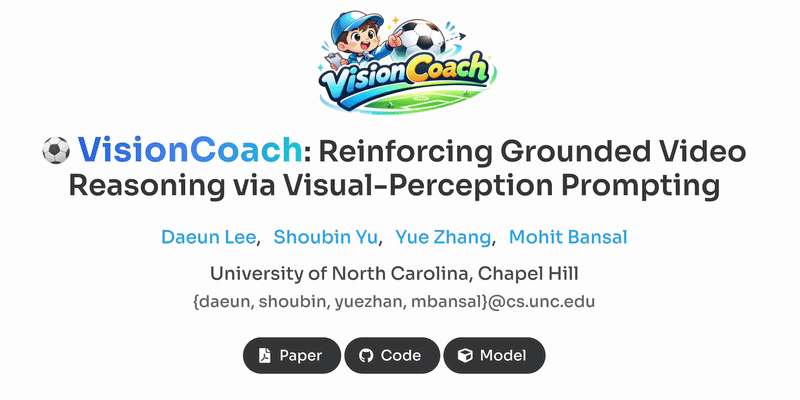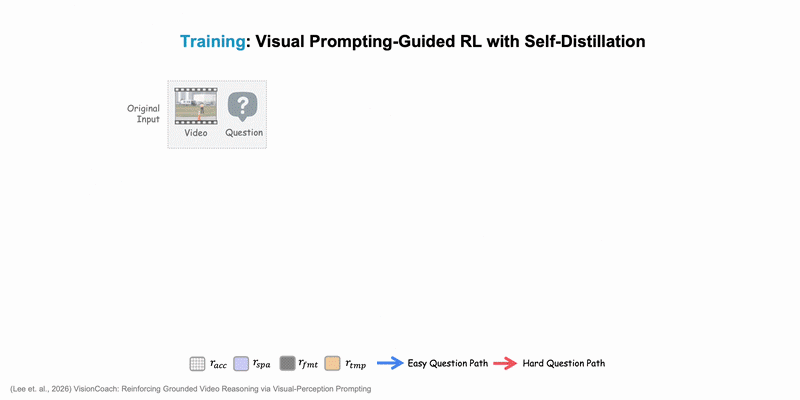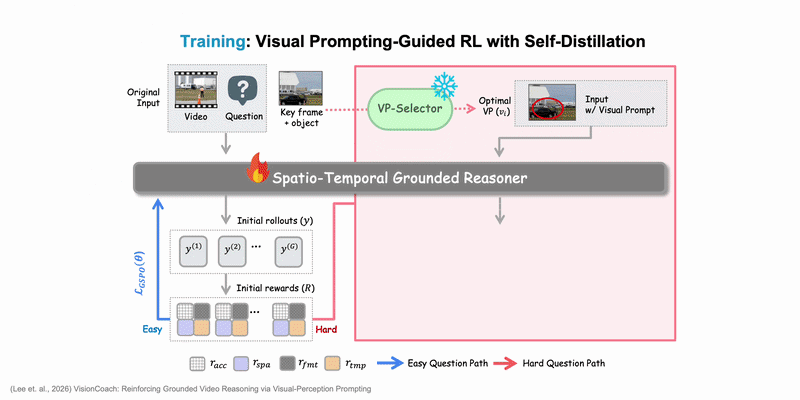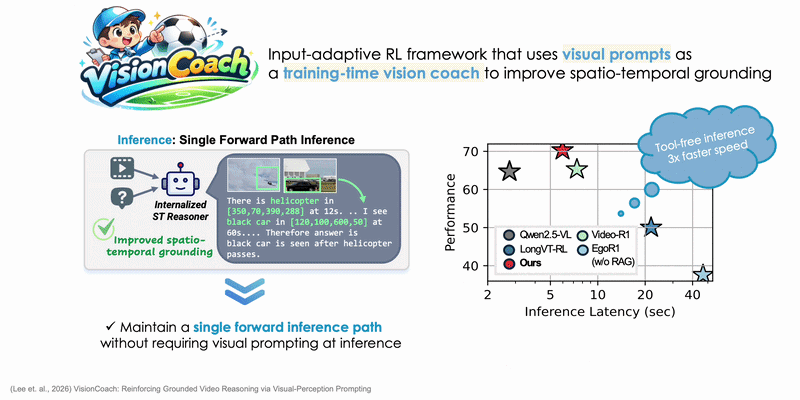
🔎 Can grounded video reasoning models self-improve via visual prompting?European Conference on Computer Vision (ECCV), 2026.
-
 ACL Findings
🔎 Can text-to-video models detect and self-repair their own errors?The 64th Annual Meeting of the Association for Computational Linguistics (ACL) Findings, 2026.
-
 EMNLP Findings
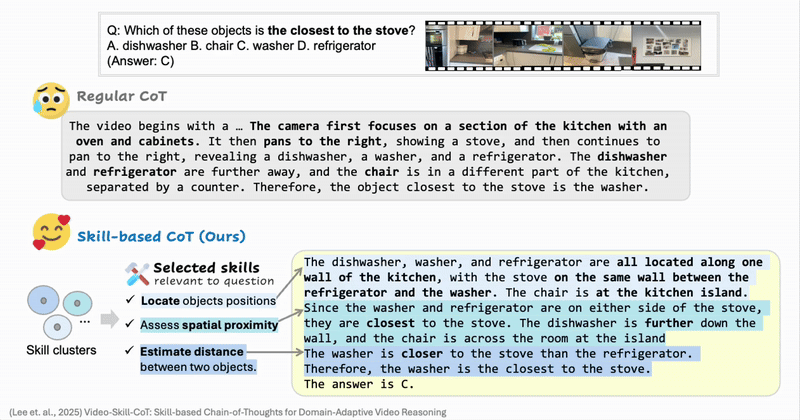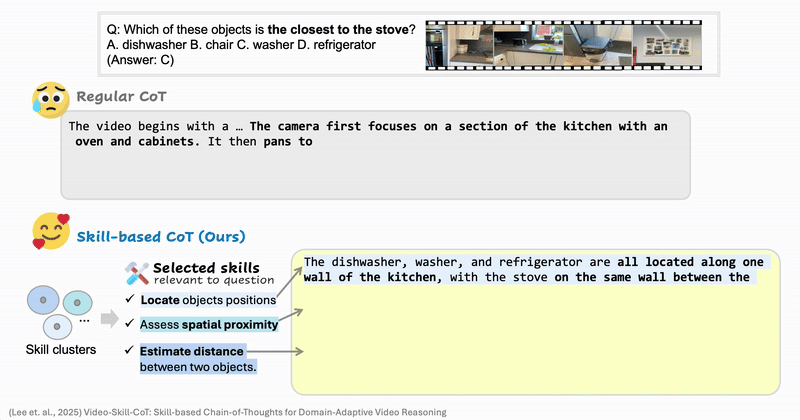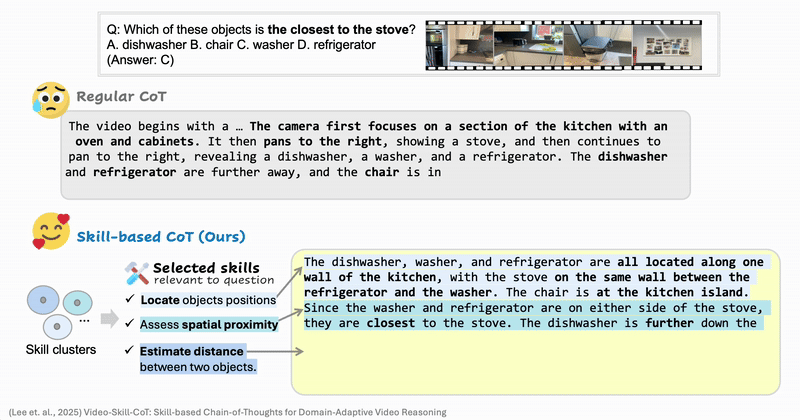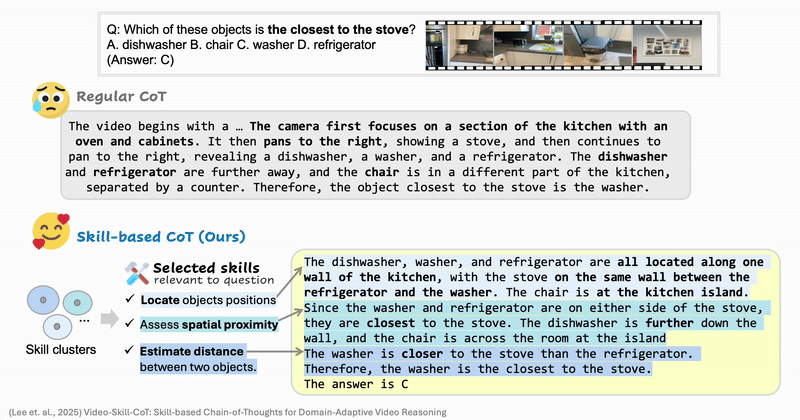
🔎 Can skill-based reasoning help video models adapt across domains?Empirical Methods in Natural Language Processing (EMNLP) Findings, 2025.
-
 ICML
🔎 Let's use mixture-of-domain experts for efficient continual test-time adaptation!International Conference on Machine Learning (ICML), 2024.
-
 CVPRW
🔎 Can HD maps teach lane detectors to generalize across domains?CVPR Data-Driven Autonomous Driving Simulation Workshop (CVPRW), 2024.
-
 WACV
🔎 How to detect rare objects in LiDAR point clouds?IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), 2023.
-
 ECCV
🔎 Can automatic colorization generalize beyond its training domain?European Conference on Computer Vision (ECCV), 2022.
No papers in this filter yet — stay tuned! 🧸
Services
- Conference Reviewer:
- CVPR/ECCV/ICCV 2022-2026
- AAAI 2025
- NeurIPS 2025-2026
- Invited Talks:
- Sep 2025. SKKU (Sungkyunkwan University) Google Developer Groups
- Jan 2025. Cisco. ‘Reliable Text-to-Video Generation’
Misc
- I am a big fan of Sanrio (Hello Kitty, Mymelody, Kuromi), all teddy bears, and K-POP!
- I know my name Daeun (다은) can be a little tricky to pronounce! It sounds somewhat like “down” — you can hear it here. Or just call me Dana!